A server crash can become a serious problem when you are running an unmanaged VPS and no technical support team is available to diagnose the issue for you. Your website may stop loading, SSH may become unreachable, applications can fail, or the entire virtual server may suddenly appear offline.
In a managed hosting environment, the provider may assist with troubleshooting and recovery depending on the service plan. With unmanaged hosting, however, identifying operating system, firewall, application, and configuration problems is usually your responsibility. This is an important difference to understand when comparing managed vs unmanaged VPS.
If your server goes down, avoid making random configuration changes. A structured troubleshooting process can help you determine whether the problem comes from networking, resource exhaustion, disk space, failed services, firewall rules, or the hosting infrastructure.
1. Confirm Whether the Entire VPS Is Down
A website being unavailable does not necessarily mean the whole VPS has crashed.
The server may still be online while Nginx, Apache, MySQL, PHP, DNS, or another application has stopped working.
Start by checking:
Whether the website opens from another internet connection
Whether the server responds to ping, if ICMP is enabled
Whether SSH access works
Whether other services are responding
Whether the VPS dashboard reports the server as running
If SSH works but the website does not, you probably have an application or service-level problem rather than a complete VPS failure.
Identifying the scope of the outage first can prevent unnecessary troubleshooting.
2. Troubleshoot an SSH Not Responding VPS
When SSH stops working, many administrators immediately assume that the server has crashed. However, an SSH not responding VPS can have several possible causes.
SSH may become unavailable because:
The SSH service stopped
A firewall blocked the SSH port
CPU usage reached an extreme level
Available memory was exhausted
The disk became full
Network configuration failed
The VPS was powered off
Try a verbose SSH connection:
ssh -vvv user@server-ipThe output can provide useful clues.
A timeout may suggest a network, firewall, or server availability problem. A "connection refused" response usually means the server can be reached, but the SSH service is not accepting connections.
3. Use the VPS Console
If SSH is unavailable, check whether your provider offers a browser console, serial console, VNC console, or rescue environment.
Console access bypasses normal SSH connectivity and can help you determine whether Linux is still responding.
Once connected, check the server's basic condition:
uptime
free -m
df -h
top
These commands quickly show system uptime, memory availability, disk usage, and active processes.
For administrators trying to fix a crashed Linux server, console access is often the fastest way to regain visibility into the system.
If the console itself is unavailable, the issue may be related to the VPS platform rather than your operating system.
4. Check CPU and Memory Usage
Resource exhaustion can make a VPS so slow that it appears completely offline.
Use:
topor:
htopif available.
Look for processes consuming unusually high CPU or memory.
Check memory separately:
free -mIf memory and swap are exhausted, Linux may terminate applications using the Out of Memory killer.
You can look for related messages with:
dmesg | tail -50If one application is responsible for excessive resource consumption, restarting the affected service may temporarily restore availability. However, investigate what caused the spike so the same outage does not happen again.
5. Check Available Disk Space
A full disk can cause websites, databases, logging systems, and other services to fail.
Run:
df -hCheck the root filesystem and important partitions such as /var.
If usage is close to 100%, investigate large files or directories:
du -sh /var/*Logs can sometimes consume large amounts of disk space:
du -sh /var/log/*Do not delete files without understanding their purpose. Important logs may contain the evidence you need to determine why the server failed.
Clean unnecessary data carefully and configure appropriate log rotation where needed.
6. Verify Web Server and Database Services
If Linux is running normally but your website remains unavailable, check the services your application depends on.
For Nginx:
systemctl status nginxFor Apache:
systemctl status apache2For MySQL:
systemctl status mysqlIf a service has failed, examine its logs before restarting it.
For example:
journalctl -u nginx --since "30 minutes ago"Logs may reveal syntax errors, missing files, permission problems, memory issues, or configuration failures.
Understanding why a service stopped is more valuable than repeatedly restarting it.
7. Review System Logs for the Root Cause
Logs are essential when you need to troubleshoot a VPS offline.
Start with:
journalctl -xeDepending on your Linux distribution, you may also review /var/log/syslog or /var/log/messages.
Look for errors that appeared shortly before the outage, including:
Out-of-memory events
Filesystem errors
Failed services
Network errors
Authentication failures
Application crashes
Kernel problems
Focus on the timeline. If the server became unavailable at a specific time, check what happened immediately before that moment.
8. Review Firewall Configuration
A server may be operating normally while incorrect firewall rules prevent users from reaching it.
For UFW, check:
ufw statusFor firewalld:
firewall-cmd --list-allFor nftables:
nft list rulesetConfirm that required ports such as SSH, HTTP, and HTTPS remain accessible.
If you recently changed firewall rules, that change deserves particular attention.
Remember that some VPS providers also provide a network-level firewall. In that case, check both the provider firewall and the firewall running inside Linux.
9. Test Networking and DNS
If services appear healthy but the VPS remains inaccessible, test network configuration.
Check interfaces:
ip addrCheck routing:
ip routeThen test external connectivity:
ping 8.8.8.8If this works, test DNS:
ping google.comIf IP connectivity succeeds but domain resolution fails, DNS configuration may be the problem.
Your own website's DNS should also be checked. Use:
dig yourdomain.comConfirm that the domain points to the correct VPS IP address.
A DNS problem can make a healthy server look offline to website visitors.
10. Review Recent Server Changes
Recent changes are often the best clue when a VPS suddenly fails.
Consider whether you recently:
Updated server packages
Changed firewall rules
Modified SSH settings
Edited Nginx or Apache configuration
Updated PHP
Changed database settings
Installed security software
Deployed new application code
If the outage began immediately after one of these actions, review or roll back that specific change instead of modifying unrelated parts of the server.
11. Should You Reboot the VPS?
Restarting a server can restore temporary functionality, but it should not automatically be your first action.
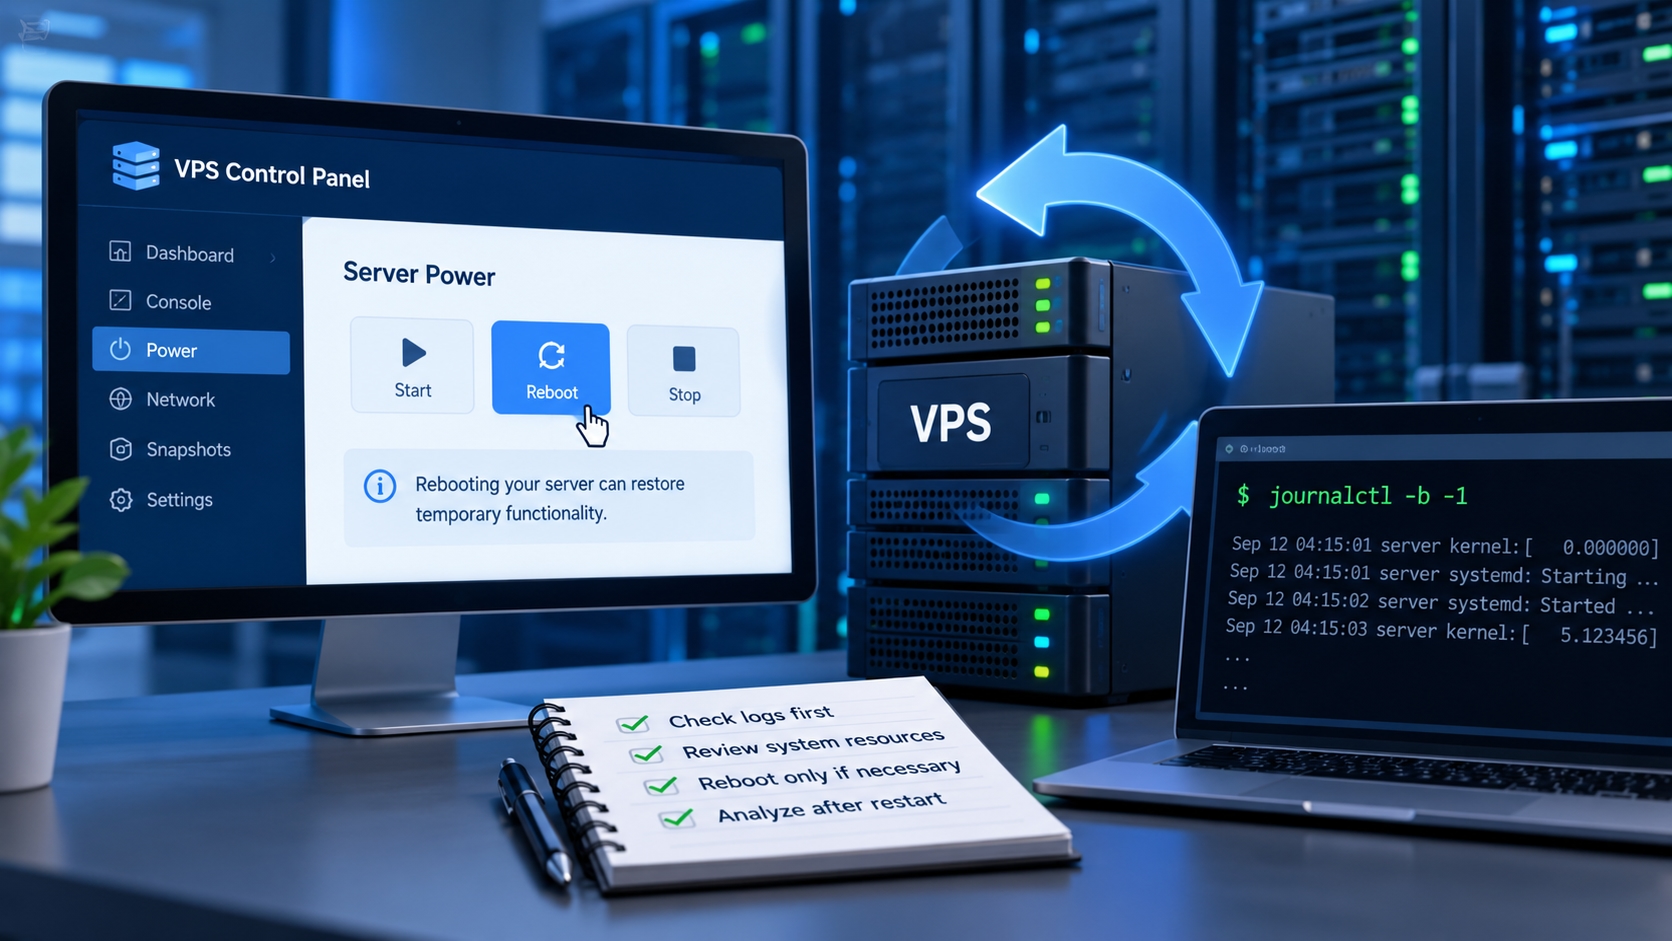
If console access still works, check logs and system resources before rebooting. Otherwise, valuable evidence about the cause of the outage may disappear.
If the system is completely frozen or inaccessible, a reboot from the provider dashboard may be necessary.
After the server comes back online, check logs from the previous boot:
journalctl -b -1This can help explain what happened before the crash.
12. Know When the Provider Should Help
Unmanaged hosting does not mean the provider has no responsibility.
The hosting company normally remains responsible for its physical servers, virtualization platform, storage infrastructure, and network.
Contact the provider if:
The VPS cannot be started
The web console is unavailable
The virtual disk cannot be accessed
Network connectivity fails despite correct configuration
You suspect a host-node failure
Linux administration, application configuration, software errors, and firewall problems may fall outside standard unmanaged hosting support help.
Checking the provider's support policy beforehand helps you understand where its responsibility ends.
Prepare Before the Next Server Crash
Good preparation makes future outages easier to manage.
Keep records of your server IP, SSH settings, console access method, firewall configuration, DNS provider, important services, recent changes, and backup locations.
Most importantly, maintain backups outside the VPS itself. If the server or virtual disk becomes unavailable, a backup stored only on that same machine may not help.
Final Thoughts
Recovering an unmanaged VPS requires a systematic process rather than trial and error.
First determine whether the entire server is offline or only a particular application has failed. Then test SSH and console access, check CPU and memory usage, inspect disk space, verify important services, review logs, examine firewall rules, and test networking and DNS.
Unmanaged VPS hosting provides significant control, but that control also means taking responsibility for troubleshooting and server recovery. Businesses without Linux administration experience should consider whether they have the skills and availability required to manage unexpected outages.
Reliable backups, documented configurations, server monitoring, and a clear recovery checklist can significantly reduce the impact of the next server failure.
Frequently Asked Questions
What should I check first when an unmanaged VPS goes offline?
Check whether the entire VPS is unreachable or only the website has failed. Test SSH, review the provider dashboard, and use console access if available.
Why might SSH stop responding?
Common causes include a stopped SSH service, firewall rules, memory exhaustion, high CPU usage, network problems, or a full disk.
Can I fix a crashed Linux VPS myself?
Many operating system and application problems can be diagnosed using console access, service status commands, logs, and resource checks. Infrastructure failures normally require provider assistance.
Should I reboot the VPS immediately?
Not necessarily. Review logs and system resources first when possible. Reboot when the server is frozen or normal troubleshooting access is unavailable.
What support does an unmanaged VPS provider normally offer?
Providers generally handle their underlying hardware, network, virtualization, and infrastructure. Operating system and software troubleshooting may remain the customer's responsibility.